In this guide
A podcast editor has a clean interview, a finished MP4, and one problem: a music bed sits underneath every answer. Lowering the soundtrack also lowers the dialogue, while a conventional noise reducer may treat the music as wanted audio. The useful question isn't how to mute the video. It's which sound should remain audible after separation.
Text-guided isolation approaches the mix differently. The editor names one audible source, reviews the resulting tracks, and chooses the output that fits the edit. That distinction matters for interviews, social clips, course recordings, and podcast snippets, where intelligible speech usually matters more than completely silent background audio.
What You Are Actually Isolating
A speaker pauses, the music bed continues, and the next sentence exposes whether the separation worked. A finished video usually contains one mixed audio track. Spoken voice, music, room tone, sound effects, and compression artifacts have already been combined, so there may be no original dialogue stem available to mute. Removing background music means separating a target source from that mixture.
For a dialogue-led interview, the practical target is spoken voice. Tell the isolation system to preserve that source, then listen to the speech-focused output. The background output deserves equal attention because it shows whether music has been reduced or still leaks through pauses, breaths, and consonants.
Isolation is not volume control
A volume fade lowers the entire track, or a separately available music layer. Noise reduction targets characteristics such as hiss or environmental rumble. This guide to audio isolation versus noise reduction explains the difference: source separation distinguishes one audible element from other overlapping elements.
Music often shares frequencies with speech, which makes the task imperfect. A vocal-heavy song, bright percussion, or dense orchestration can occupy the same range that gives dialogue its presence. The system may preserve the voice while leaving faint music behind, or remove some wanted vocal tone with the accompaniment. In dense mixes, inspect difficult passages before committing to the processed track.
Practical rule: Name the sound that should survive, not only the sound that should disappear.
Source separation has progressed from research prototypes to practical consumer workflows. Commercial four-stem tools arrived in late 2018, and Deezer released Spleeter as open source in 2019, helping mainstream users split vocals from accompaniment. By 2022, Meta's Hybrid Transformer Demucs reported 9.00 dB average SDR on the MUSDB HQ test set. This overview of stem separation history provides context for those developments and for the changing quality of separation tools.
The original mix still sets the ceiling. A clean result may preserve the interview while retaining a little ambience. That can sound more natural than aggressive processing that makes the speaker brittle, hollow, or overly isolated.
For a short clip, use a clear decision sequence: isolate dialogue, inspect the result, and decide whether the remaining artifacts are acceptable. Comparing the isolated output with the background output reveals problems that a quick volume check can miss.
Uploading Video and Writing Effective Prompts
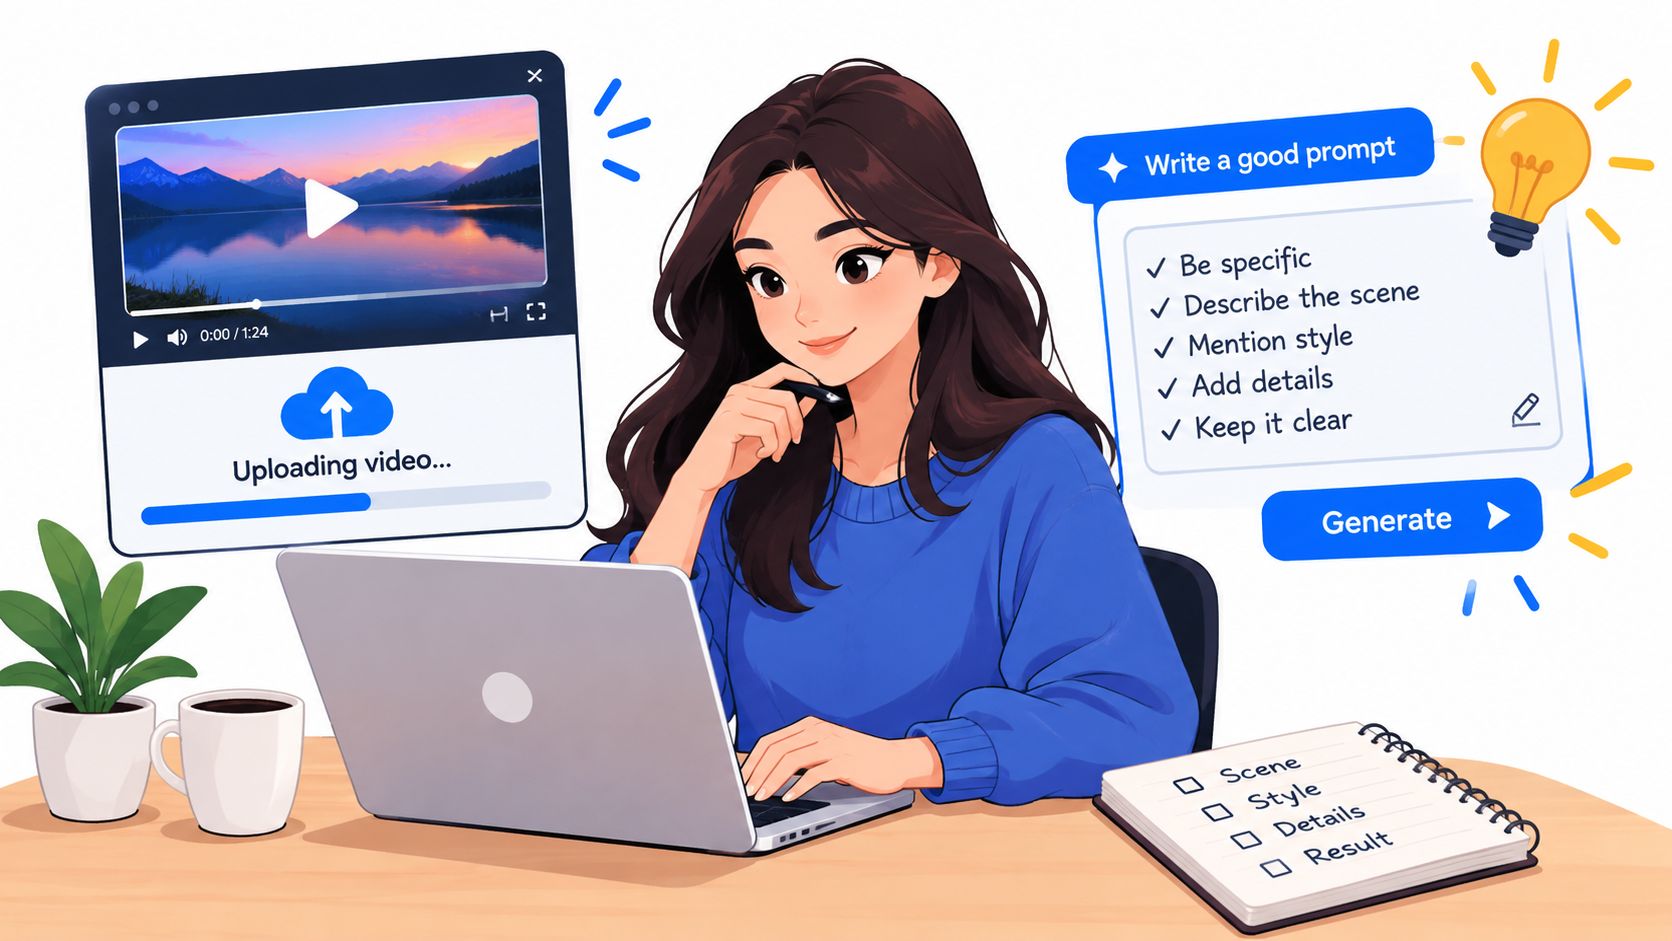
The browser workflow starts with a source file and a precise target. Saturalabs is a text-guided audio and video isolation service, not a general video editor or a music generator. It separates an audible source from an uploaded recording, while timing, captions, cuts, transitions, and final video assembly remain in the editor.
Supported uploads include MP3, WAV, MP4, and MOV files up to 50 MiB (52.43 MB). For a video project, MP4 or MOV is usually the most direct starting point because the editor can later align the processed audio with the picture. A WAV export can make sense when the video has already been separated from its soundtrack, but unnecessary conversion can add another step.
Prepare the file before separation
A short test segment is safer than committing a long recording immediately. The excerpt should contain a normal speech passage, a section where music overlaps the voice, and a pause where residual music will be easy to hear. If the source file exceeds the upload limit, the editor should create a representative clip or export the audio separately rather than reducing quality blindly.
Prompt wording should identify one audible source per prompt. The model needs a clear target, not a paragraph of production direction. Useful examples include:
spoken voicemale interviewfemale narrationdialogue from the interviewspoken podcast host
The strongest prompt is often the shortest accurate one. Long strings of quality adjectives, such as “clean, crisp, studio-quality, warm, professional spoken voice,” don't necessarily help the system distinguish dialogue from music. They can also make the instruction less focused.
Use a single-source rule
The audio isolation prompt guide gives broader prompt guidance, but the operational rule for this task is narrow:
- Name one source: Use “spoken voice” rather than “voice, music, ambience, and room tone.”
- Describe the audible target: Identify “female narration” if that is the dominant source.
- Avoid mixing goals: Don't ask for dialogue isolation and a final mastered mix in the same prompt.
- Test representative audio: Include overlap, pauses, and dense music rather than only a quiet opening.
The unwanted music doesn't need an elaborate description. A prompt such as “background music” can be useful when the workflow specifically targets that source, but a dialogue-preservation workflow should begin by naming the speech. Clear target selection usually gives the editor more useful information than extra adjectives about the soundtrack.
Choosing the Right Output Track
After separation, two results answer different editing questions. Isolated sound keeps the source named in the prompt. Background audio contains the remaining recording with that named source removed.
For background-music removal, the correct choice depends on what the edit needs. If the prompt names spoken voice and the aim is to place clean dialogue over a new music bed, the speech-focused isolated result deserves the first audition. If the prompt names background music and the aim is to retain everything except that music, the background output is the relevant track to inspect.
| Goal in the edit | Example target | Output to inspect |
|---|---|---|
| Preserve an interview while replacing the music bed | Spoken voice | Isolated sound |
| Keep narration and room character while removing a named music layer | Female narration | Isolated sound |
| Retain the non-music mix after targeting the soundtrack | Background music | Background audio |
| Pull dialogue from a mixed social clip for a re-edit | Male interview | Isolated sound |
Match the prompt to the output
A common mistake is to choose the track based on its label rather than its audible content. “Background audio” doesn't automatically mean “clean dialogue.” It means the target named in the prompt has been removed from the remaining recording. If the target was “spoken voice,” that output will preserve the music and other non-target material instead.
For dialogue, the practical sequence is usually:
- Prompt for spoken voice or a specific narration type.
- Audition Isolated sound for speech clarity.
- Compare it with the original on overlapping passages.
- Use Background audio only when the prompt specifically targeted the music or another unwanted source.
This approach differs from simple track muting because the original video may contain only one mixed stream. An FFmpeg -an option can remove every audio stream from an output, but it can't selectively preserve speech or music by itself. This explanation of extracting, replacing, and mixing audio with FFmpeg clarifies why a command-line mute isn't the same as source separation.
Editors who hear clicks, tonal changes, or missing consonants can use the audio repair online workflow as a related diagnostic reference. The important decision remains auditory. The selected output should make the dialogue easier to edit without introducing damage that is more distracting than the original music.
Listening Checks and Comparison Workflow
Automatic separation shouldn't be accepted because the waveform looks tidy or because the first few seconds sound clean. A reliable review compares the original and processed versions at the passages most likely to expose leakage. Quiet sections can hide problems that become obvious as soon as the speaker talks over a chorus, cymbal pattern, or sustained synth.
Run a short listening audit
The editor can review the test excerpt in this order:
- Speech clarity: Listen for missing consonants, lisping, metallic tones, or a voice that sounds unusually thin.
- Music overlap: Check the point where the speaker talks over the loudest or densest part of the music.
- Dialogue pauses: Stop speaking sections often reveal musical remnants that remain under the isolated voice.
- Room continuity: Notice whether ambience suddenly changes between words or sentences.
- Edit suitability: Check whether the result still sounds natural when placed against the intended replacement bed.
The original should remain available for direct A/B comparison. A processed track can seem acceptable in isolation while sounding obviously damaged beside the source. Headphones can reveal tonal artifacts, while small speakers often expose whether the speech remains intelligible in a realistic social-video playback context.
Trust the overlapping passages, not just the quiet sections.
Decide whether to refine or recut
A different prompt phrasing can be worth trying when the first target was too broad. “Spoken voice” may be preferable to a vague instruction about “clean audio,” while “male interview” can help distinguish the intended foreground source in a dialogue-led recording. A second pass or alternate model may also help when musical remnants persist in speech gaps, though repeated processing can add further artifacts.
Users should compare the displayed credit cost before downloading large projects. The preview or audition stage is the right place to reject a weak result, not after exporting every variation. Separation also doesn't provide copyright clearance for the music, voice, footage, or replacement material. The file owner still needs appropriate rights for the source and intended use.
Some results are good enough for a short social clip, especially when the dialogue is clearly foregrounded. A broadcast-quality interview, archival recording, or dense music performance may need selective editing instead. If only a few seconds are badly affected, a re-cut, alternate take, local volume adjustment, or replacement line can preserve more quality than forcing complete removal across the entire video.
Research on video-based audio separation evaluates systems with measures including SDR, SIR, and SAR. One 2021 visual scene-graph approach reported gains of about 1.3 dB on SDR and 1.6 dB on related metrics over its closest competitor on the MUSIC and ASIW test sets, but those benchmarks don't guarantee a clean result for a particular recording. This practical discussion of video audio separation explains why artifacts, bleed, compression, and overlap still matter in production.
Why Separation Varies and When It Fails
Background-music removal is a separation problem, and the source mix determines how difficult that problem becomes. A dry interview with a quiet music bed gives the system clearer evidence than a compressed clip where the music is loud, stereo-wide, and full of vocal or percussion energy. The model choice and training domain matter too, so no single workflow guarantees perfect recovery.
Independent research illustrates that source types don't separate equally. In a data-scarce comparison across 40 source pairs and 160 test mixtures, an attention-augmented U-Net achieved a highest mean SI-SDR of +11.52 dB for music and +5.17 dB for speech. Those results indicate that music can be easier to isolate than speech in mixed material, which helps explain why dialogue-focused cleanup can leave more audible damage than a simple music extraction. The underlying comparison supports cautious expectations rather than a universal quality promise.
Common failure patterns
Several symptoms point to an overloaded mix:
- Leaked music: A melody or beat remains audible during pauses in the speech-focused track.
- Brittle dialogue: Sibilants become sharp, vowels lose body, or the speaker sounds phasey.
- Missing words: Music and speech overlap so closely that the separator removes wanted voice detail.
- Time-stretched artifacts: Transients smear or produce warbling tones after processing.
- Unstable ambience: Room tone changes abruptly between adjacent phrases.
An iterative workflow can improve some cases. A separate multi-step separation study reported consistent improvements over one-step inference in all but one case across speech enhancement and music separation. That supports inspecting the first result, refining the target or choosing another available approach, and exporting the least artifact-heavy version rather than assuming the initial pass is final.
Know when to stop
Melodic sections can overwhelm voice cues. When the music contains vocals, heavy reverb, or prominent midrange instruments, a selective re-cut may sound more professional than aggressive isolation. The same applies when the speaker is quiet, distant, heavily compressed, or recorded in a reflective room.
The practical threshold is editorial, not mathematical. If the isolated speech preserves meaning and fits the surrounding edit, minor residue may be acceptable. If artifacts pull attention away from the speaker, the correct fix may be a new take, a shorter excerpt, or a different edit point.
Next Steps and Tool Access
A dependable workflow for removing background music from a video has four decisions:
- Describe one audible target, usually spoken voice or a specific narration type.
- Choose the output that matches the edit, Isolated sound for preserved dialogue, or Background audio when the prompt targets the music.
- Audit difficult passages, especially speech over dense music and pauses between sentences.
- Review credit cost and rights, then download only after the result survives comparison with the original.
Editors can also consult the guide on stems versus audio isolation when deciding whether a simple dialogue extraction is sufficient or a more elaborate stem workflow is justified. The browser tool is most useful when the source is a mixed recording and the editor needs a focused, auditionable output before returning to the video timeline.
The Saturalabs browser tool accepts MP3, WAV, MP4, and MOV uploads up to 50 MiB (52.43 MB), then uses text-guided isolation to separate a named audible source from the rest of the recording. Editors can try it for dialogue-led video, compare the isolated and background outputs, and review current credit costs before downloading at Saturalabs.